SCALM: Towards Semantic Caching for Automated Chat Services with Large Language Models
IEEE/ACM International Symposium on Quality of Service (IWQoS), 2024
Abstract
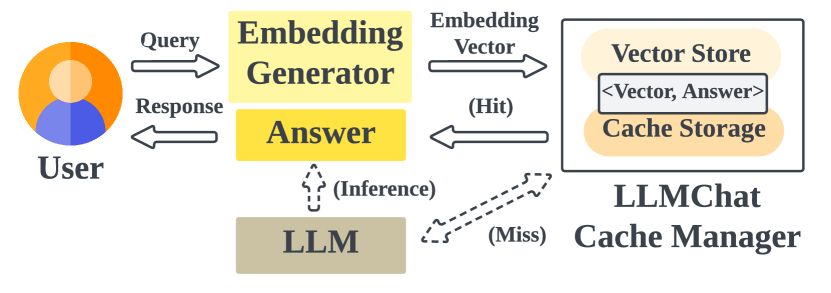
Large Language Models (LLMs) have become increasingly popular, transforming a wide range of applications across various domains. However, the real-world effectiveness of their query cache systems has not been thoroughly investigated. In this work, we for the first time conducted an analysis on real-world human-to-LLM interaction data, identifying key challenges in existing caching solutions for LLM-based chat services. Our findings reveal that current caching methods fail to leverage semantic connections, leading to inefficient cache performance and extra token costs. To address these issues, we propose SCALM, a new cache architecture that emphasizes semantic analysis and identifies significant cache entries and patterns. We also detail the implementations of the corresponding cache storage and eviction strategies. Our evaluations show that SCALM increases cache hit ratios and reduces operational costs for LLMChat services. Compared with other state-of-the-art solutions in GPTCache, SCALM shows, on average, a relative increase of 63% in cache hit ratio and a relative improvement of 77% in tokens savings.
BibTeX
@inproceedings{li2024scalm,
  title     = {{SCALM}: Towards Semantic Caching for Automated Chat Services with Large Language Models},
  author    = {Li, Jiaxing and Xu, Chi and Wang, Feng and von Riedemann, Isaac M. and Zhang, Cong and Liu, Jiangchuan},
  booktitle = {2024 IEEE/ACM 32nd International Symposium on Quality of Service (IWQoS)},
  pages     = {1--10},
  year      = {2024},
  doi       = {10.1109/IWQoS61813.2024.10682957}
}